Capability proof · Targeting
Bank Marketing — contact-cost efficiency
A targeting model built to a decision, with a pilot recommendation rather than a deployment.
- My role
- Independent analyst · Sole contributor
- Period
- 2026 · Approximately 2 weeks
- Engagement
- Self-directed case study; completed individually
Business objective: Prioritise likely responders within a limited outreach capacity, and define a controlled validation pilot.
My ownership: I completed this project independently from end to end: framed the question, prepared and validated the data, performed the analysis, built the reporting output, and wrote the recommendations and limitations.
The dataset is a widely-used teaching set and credit and risk is not a lane I am pursuing. What transfers is the targeting economics — capture, lift and contact cost against a fixed call capacity — rather than the domain.
With limited call capacity, which customers should a telemarketing team contact first? The useful metric is not accuracy — it is how much of the responder population a realistic workload captures.
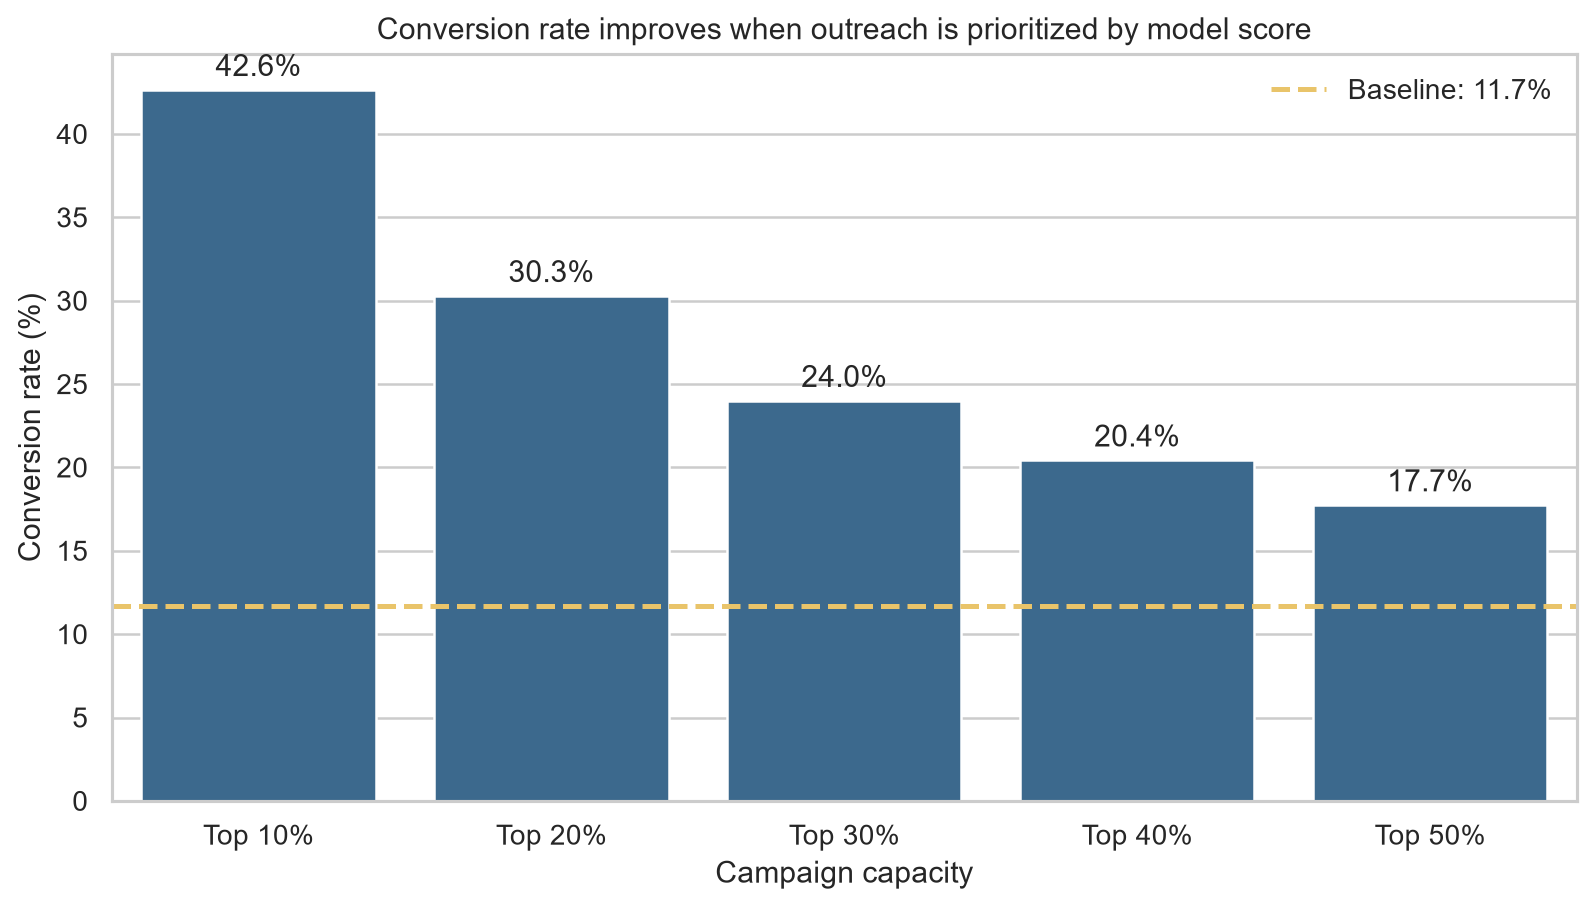
With call capacity fixed, the top-ranked 20% of customers captures 51.8% of historical responders at 30.3% conversion — 2.59× lift — while cutting outreach volume 80%. Because the data is observational, the recommendation is a randomised pilot rather than deployment: a historical ranking does not establish that contacting someone causes a response.
- Built to the decision, not to the metric. The constraint is call capacity, so the model is evaluated on capture and lift within a contact band rather than on overall accuracy.
- Excluded the leakage. Post-contact and campaign-execution fields were removed. A model that knows the call outcome predicts the call outcome.
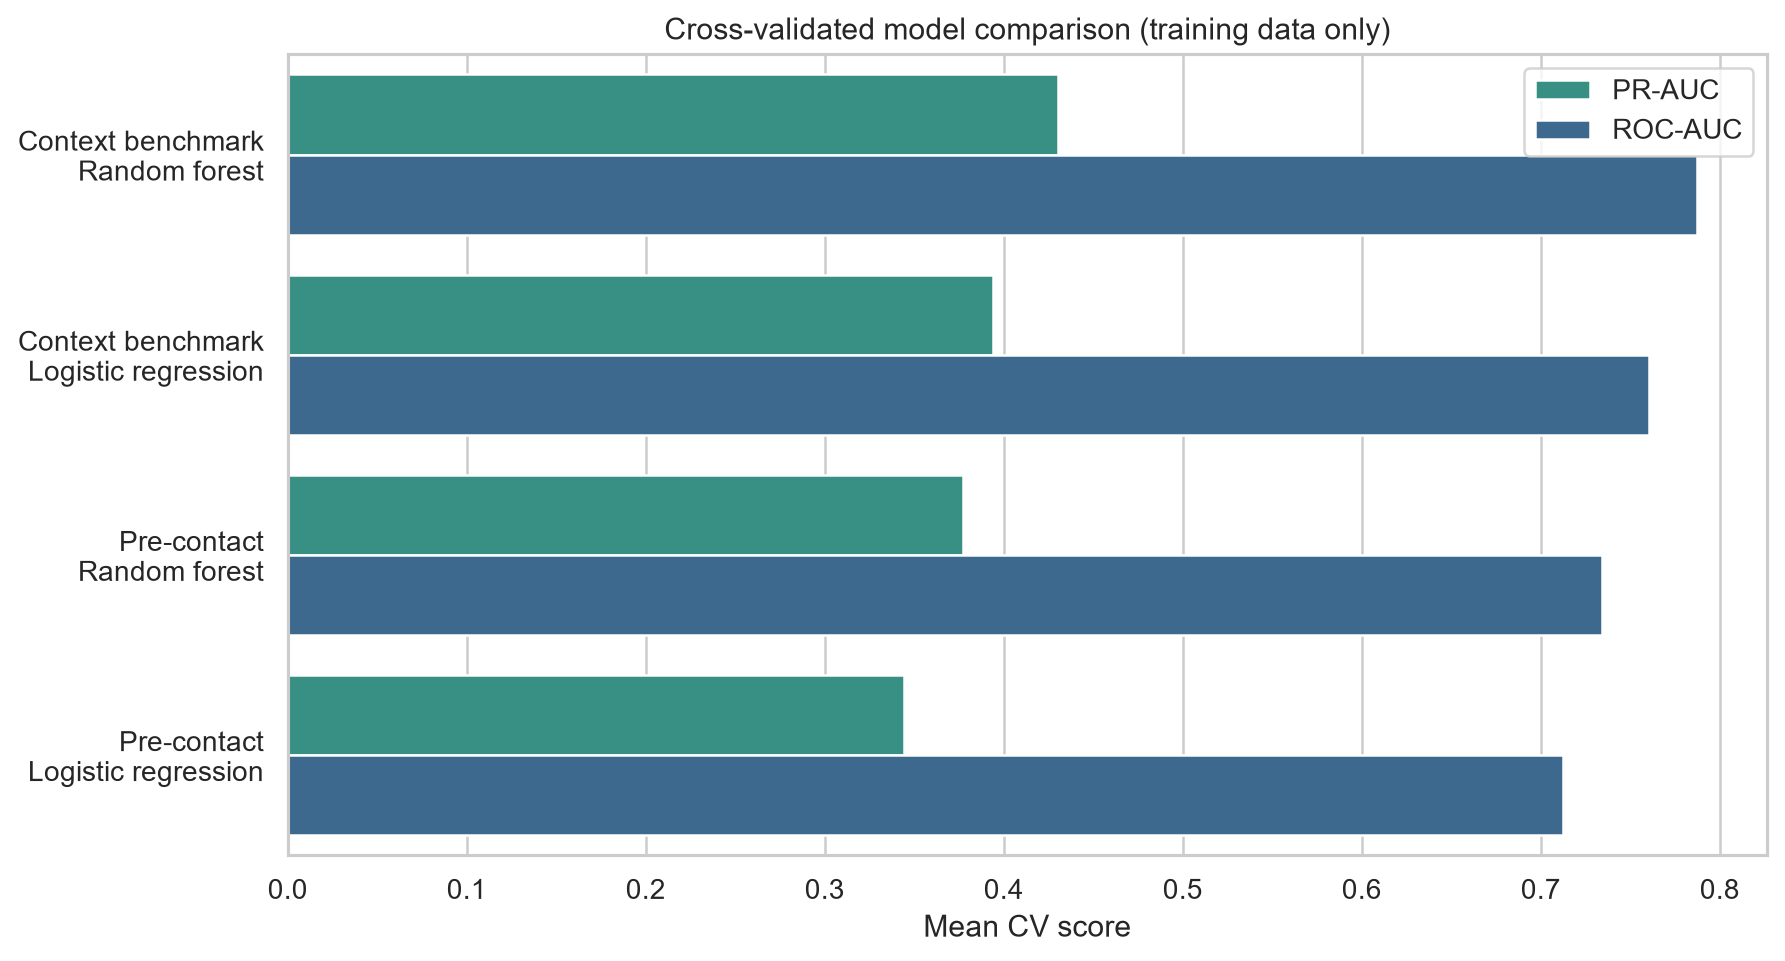
- Compared on an untouched test set. Logistic regression against random forest, stratified cross-validation, and an untouched test set. Pre-contact random forest selected: ROC-AUC 0.738, PR-AUC 0.384 against an 11.7% base rate.
What the evidence says
What it found.
A realistic workload captures half the responders
The top-ranked 20% captures 51.8% of historical responders at 30.3% conversion — 2.59× lift — while cutting outreach volume 80%.
Which is a historical ranking, not a campaign uplift
The model ranks who responded before. It does not establish that contacting them causes a response, and the two are not the same claim.
What it looks like
The output, not a description of it.
- Observational data, so the recommendation is a randomised pilot rather than deployment. Historical ranking does not establish incremental response.
- Fairness and business-value guardrails were specified as conditions of the pilot, not added afterwards.
- The dataset is a teaching set. Nothing in the findings is new. The constraint, the evaluation against it and the pilot recommendation are what the work consists of.